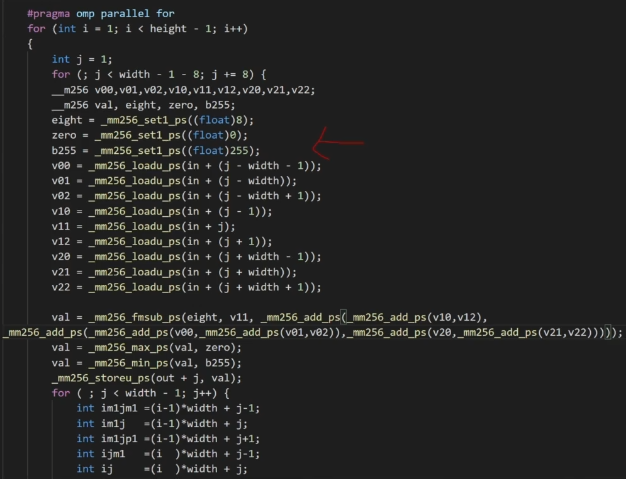
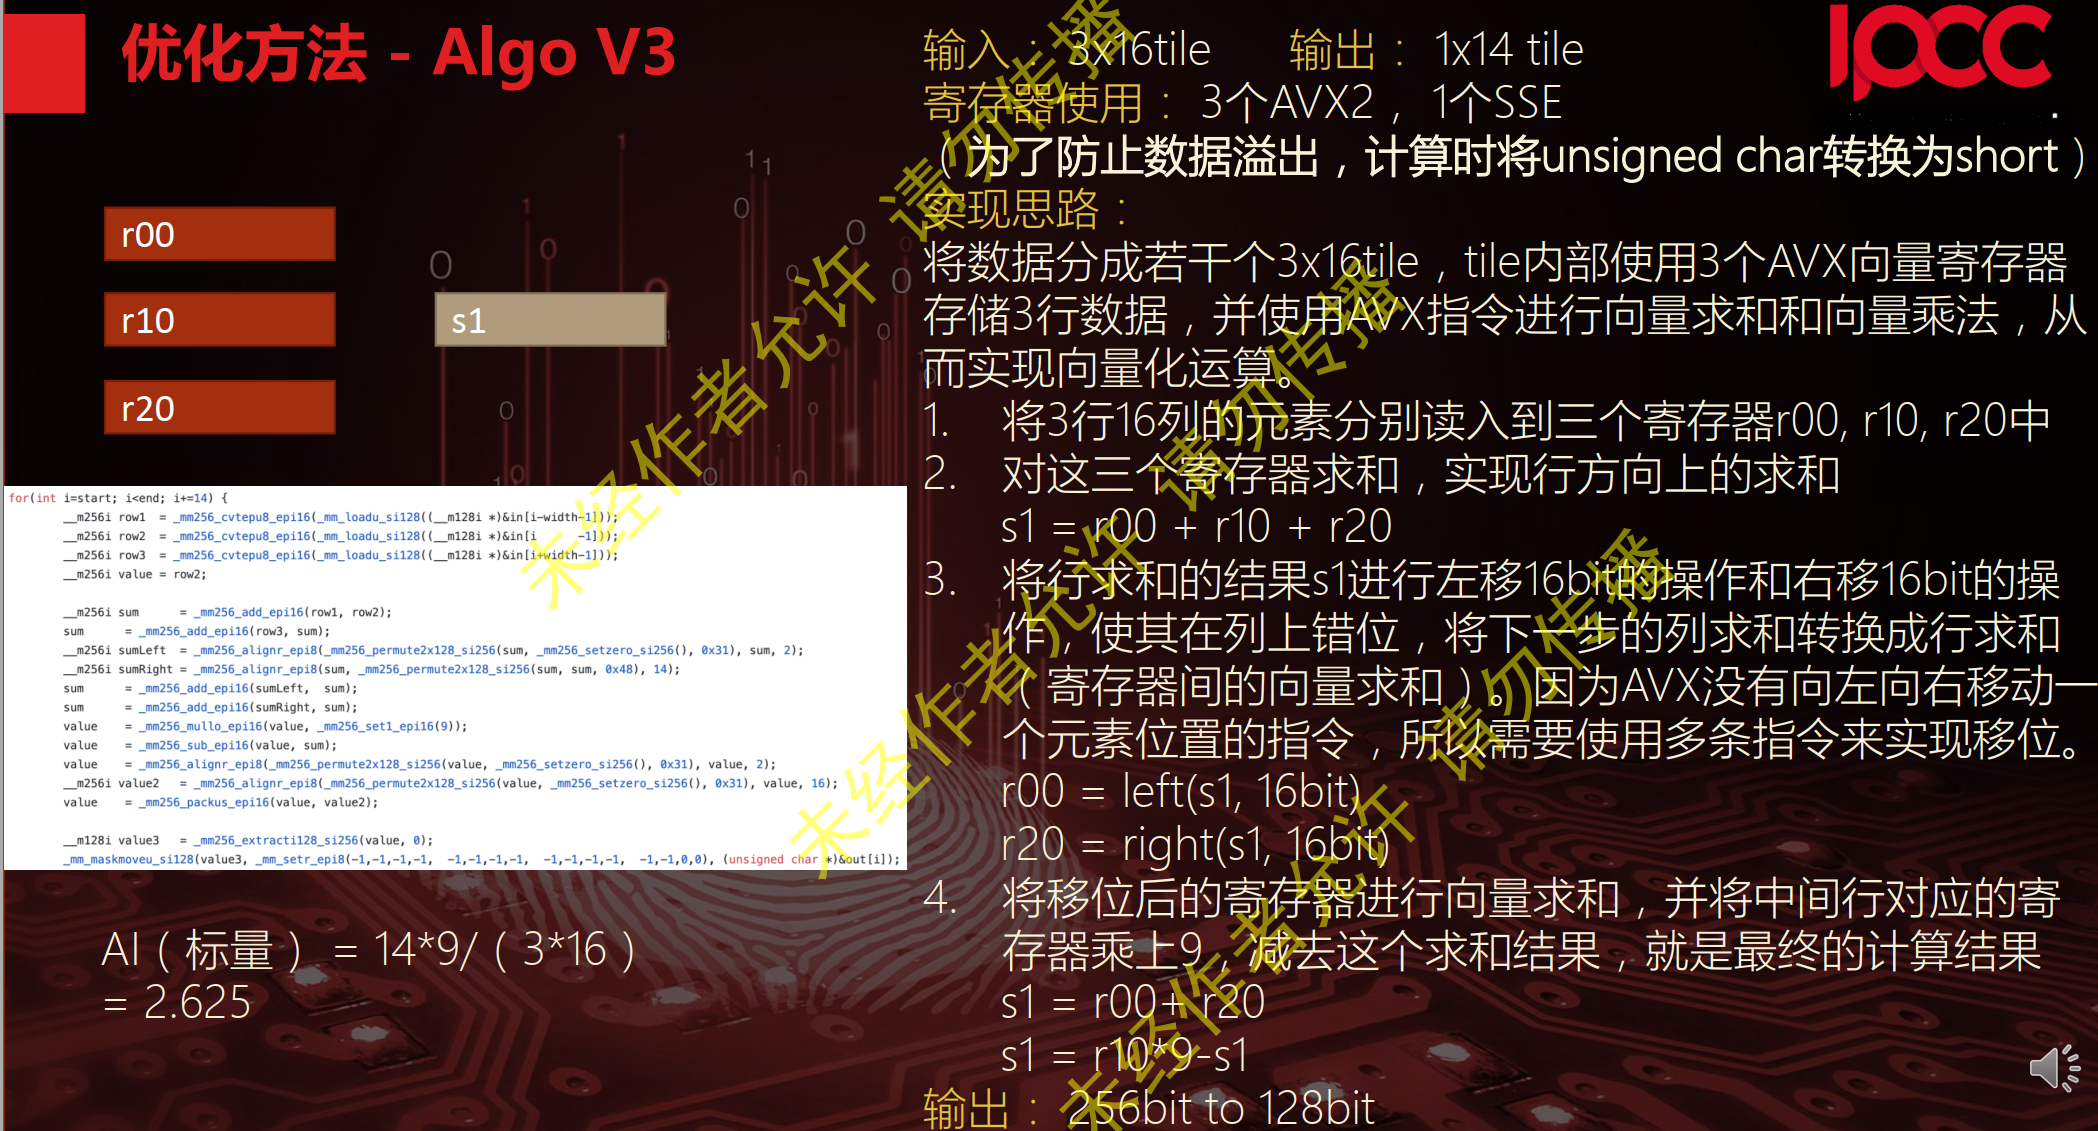
_mm256_hadd_epi16 // Horizontally add eg.dst[15:0] := a[31:16] + a[15:0]
_mm256_mulhi_epi16 // Multiply the packed signed 16-bit integers in a and b, producing intermediate 32-bit integers, and store the high 16 bits of the intermediate integers in dst.
_mm256_sign_epi16 // 根据b的值,将-a/0/a存入dst
// 乘加,乘减,的计算组合也有
We also plan to release the source code of our tool as open source
1 简介
2 相关工作
Information provided by Intel
Measurement-based Approaches
3 Background
Pipeline of Intel Core CPUs
Assembler Instructions
Hardware Performance Counters
4 Definitions
Latency
Throughput
Port Usage
5 Algorithms
Port Usage
Finding Blocking Instructions
Port Usage Algorithm
Latency
Register -> Register
Both registers are general-purpose registers
Both registers are SIMD registers
The registers have different types
Memory → Register
Status Flags → Register
Register → Memory
Divisions
Throughtput
Measuring Throughput
Computing Throughput from Port Usage
Computing Throughput from Port Usage
Details of the x86 Instruction Set
Measurements on the Hardware
Analysis Using Intel IACA
Machine-readable Output
7 Evaluation
balabala~
8 Limitations
9 Conclusions and Future Work
我们的工具可以用来优化llvm-mca等软件。
Future work includes adapting our algorithms to AMD x86 CPUs. 官网已经实现了。
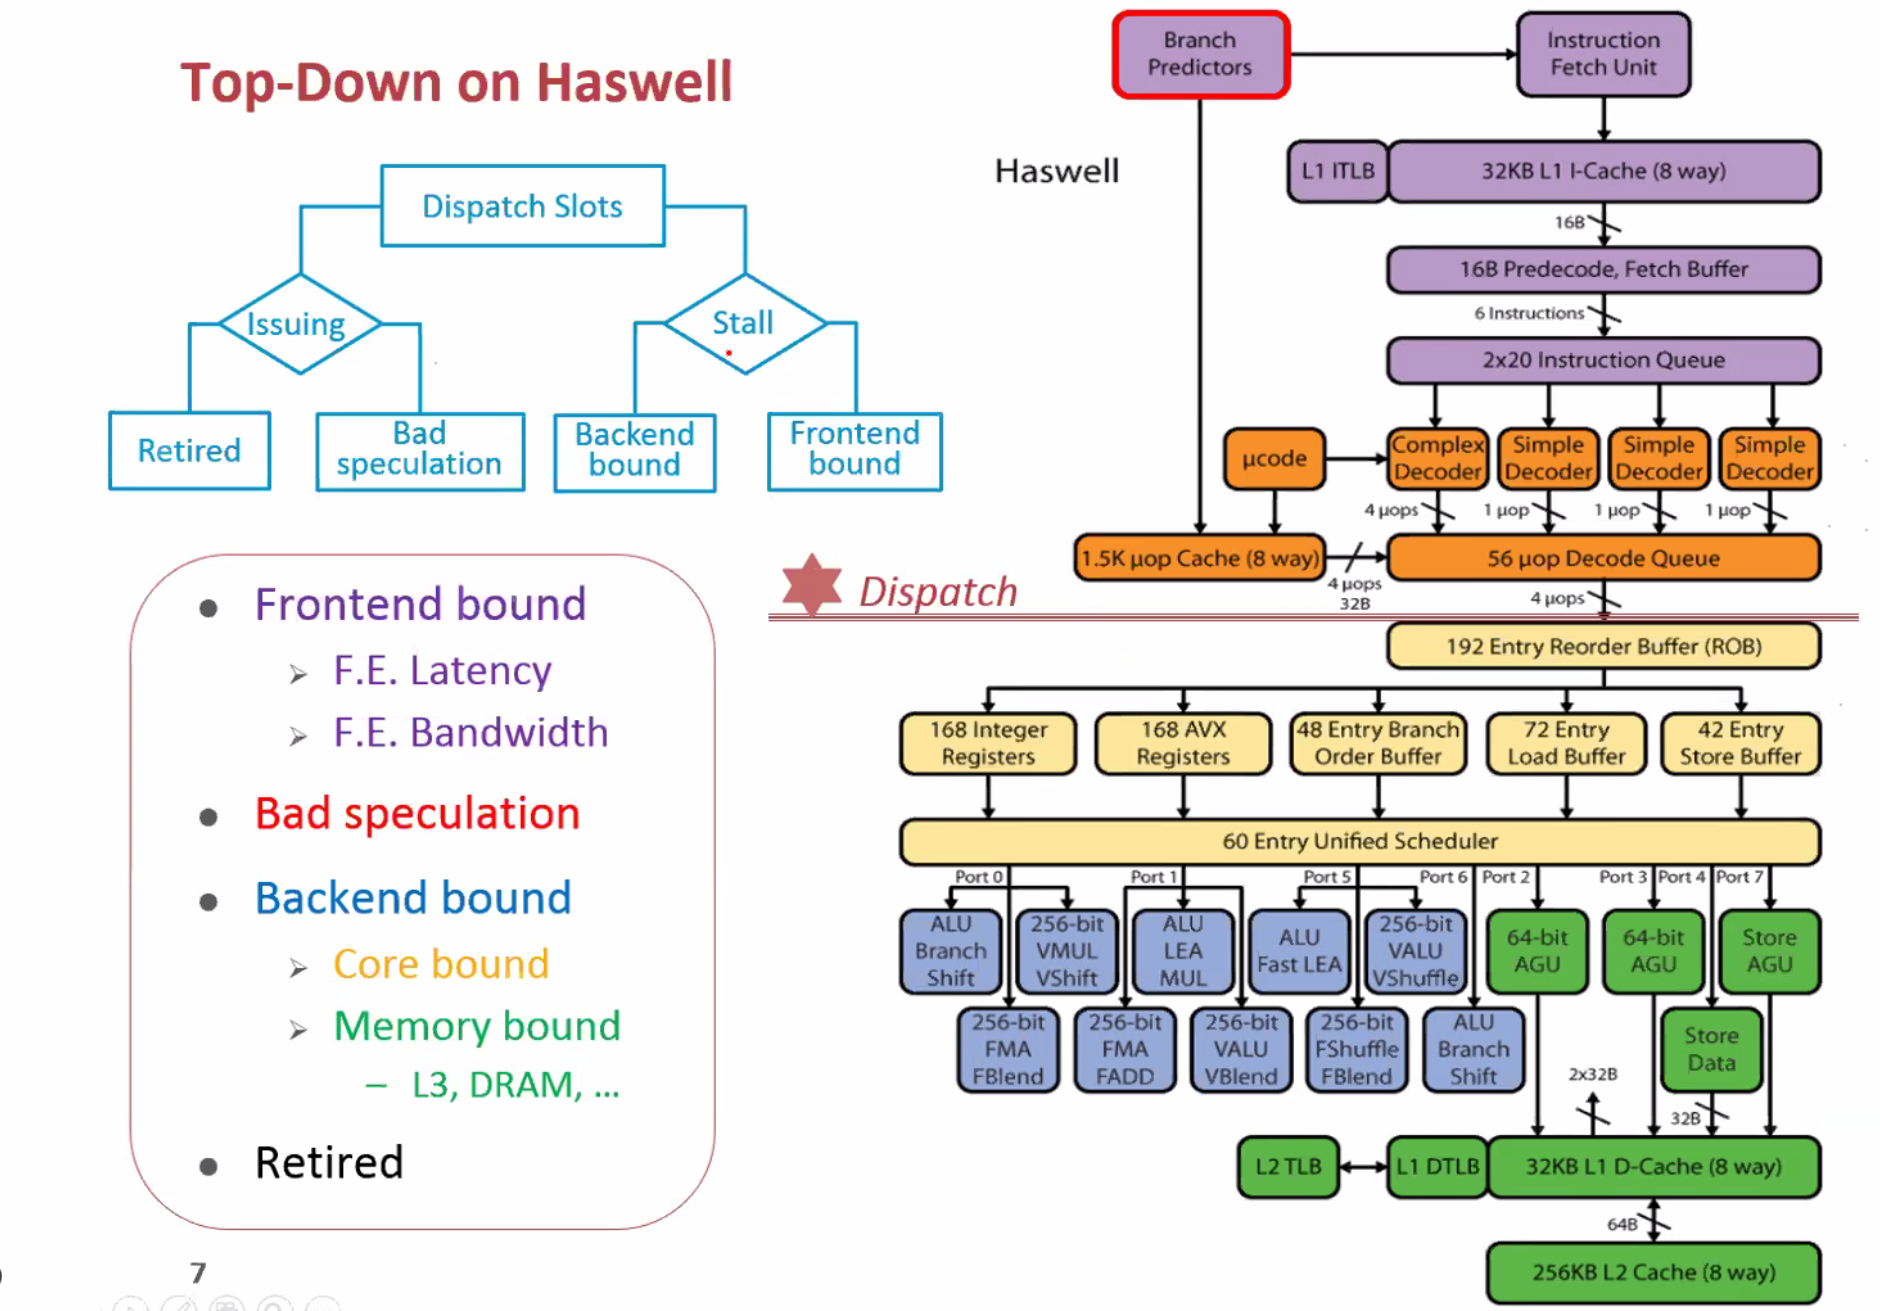
We would also like to extend our approach tocharacterize other undocumented performance-relevant aspects of the pipeline, e.g., regarding micro and macro-fusion, or whether instructions use the simple decoder, the complex decoder, or the Microcode-ROM.
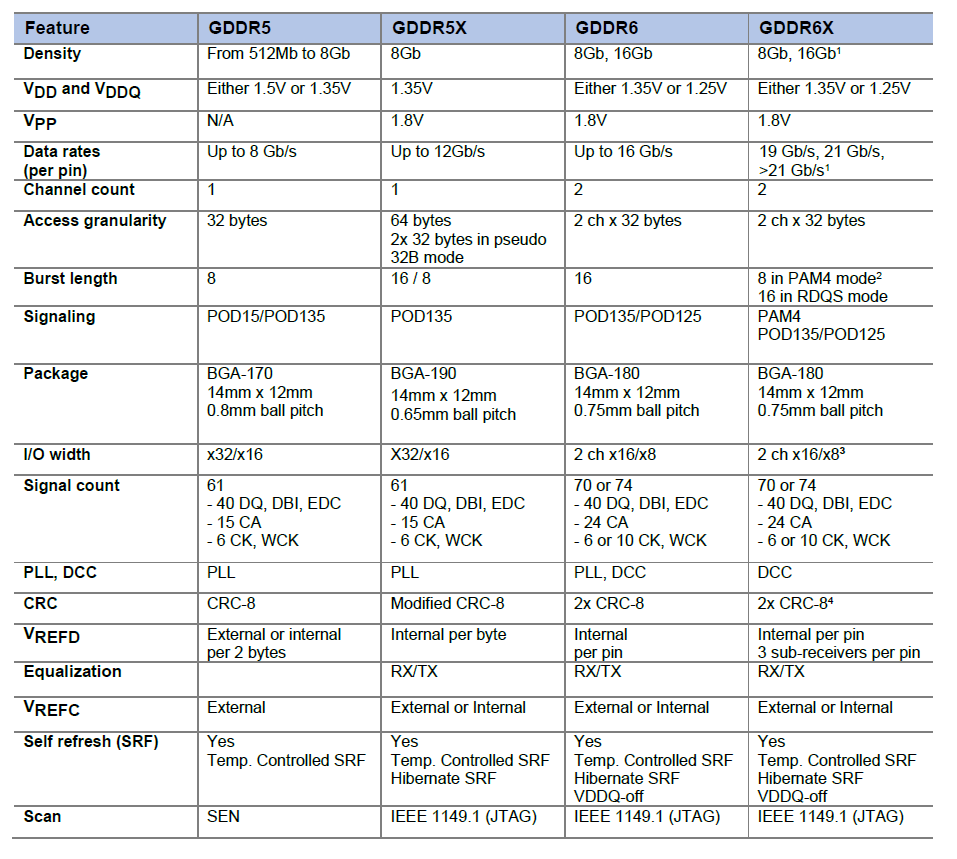
显卡能让显存达到更高的频率显存颗粒与GPU配套使用时,一般都经过专门的设计和优化,而不像内存那样有太多顾忌。GPU的显存控制器比CPU或北桥内存控制器性能优异,而且显卡PCB可以随意的进行优化,因此显存一般都能达到更高的频率。而内存受到内存PCB、主板走线、北桥CPU得诸多因素的限制很难冲击高频率。由此算来,显存与内存“分家”既是意料之外,又是情理之中的事情了。为了更好地满足显卡GPU的特殊要求,一些厂商(如三星等)推出了专门为图形系统设计的高速DDR显存,称为“Graphics Double Data Rate DRAM”,也就是我们现在常见的GDDR。